

Reinforcement learning for routing
1.6% from optimal on TSP20
Optimality gap vs. LKH across 1,000 test graphs. Lower is better.
This work Classical baselines
Open to roles · Summer & Fall 2027
Data Scientist AI Architect Data Engineer
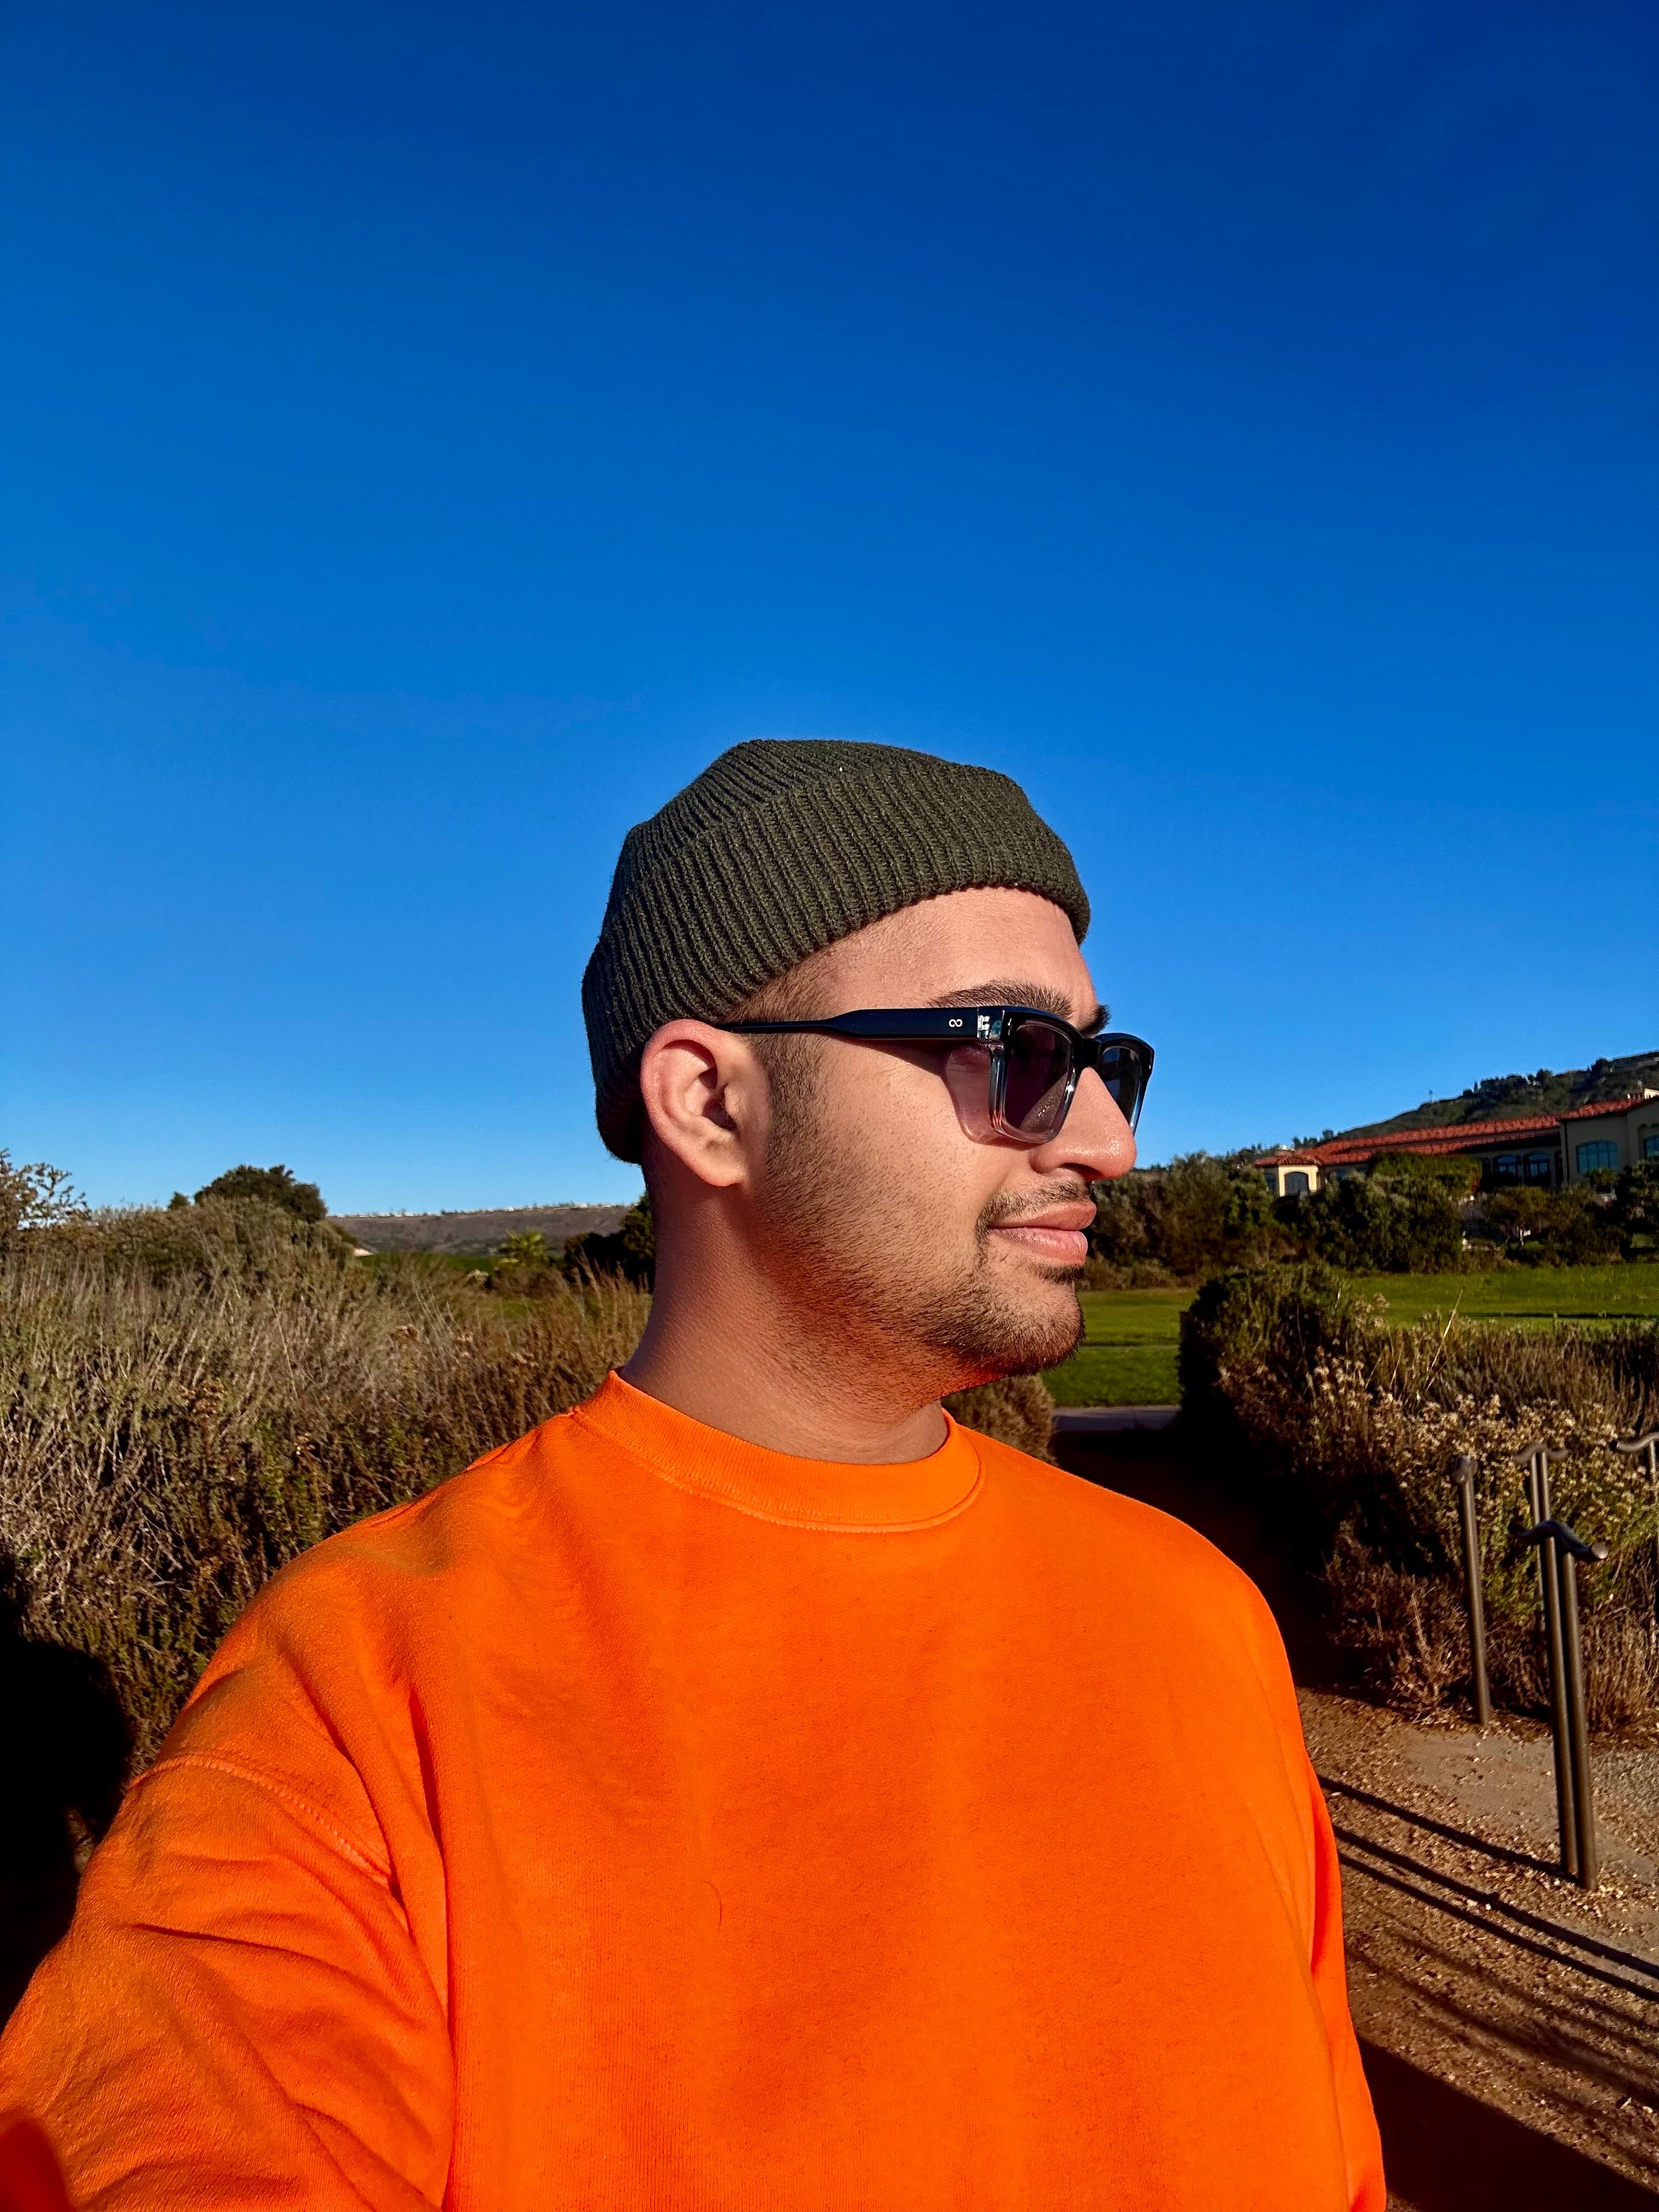
Data scientist specializing in NLP and large language models, with a data engineer's discipline for pipelines and an architect's eye for systems. Published research on LLM-based machine translation at RANLP 2025 and ICAI 2026.
Proven results
Results from published research and reproduced experiments, and the pipelines behind them.
Reinforcement learning for routing
Optimality gap vs. LKH across 1,000 test graphs. Lower is better.
This work Classical baselines
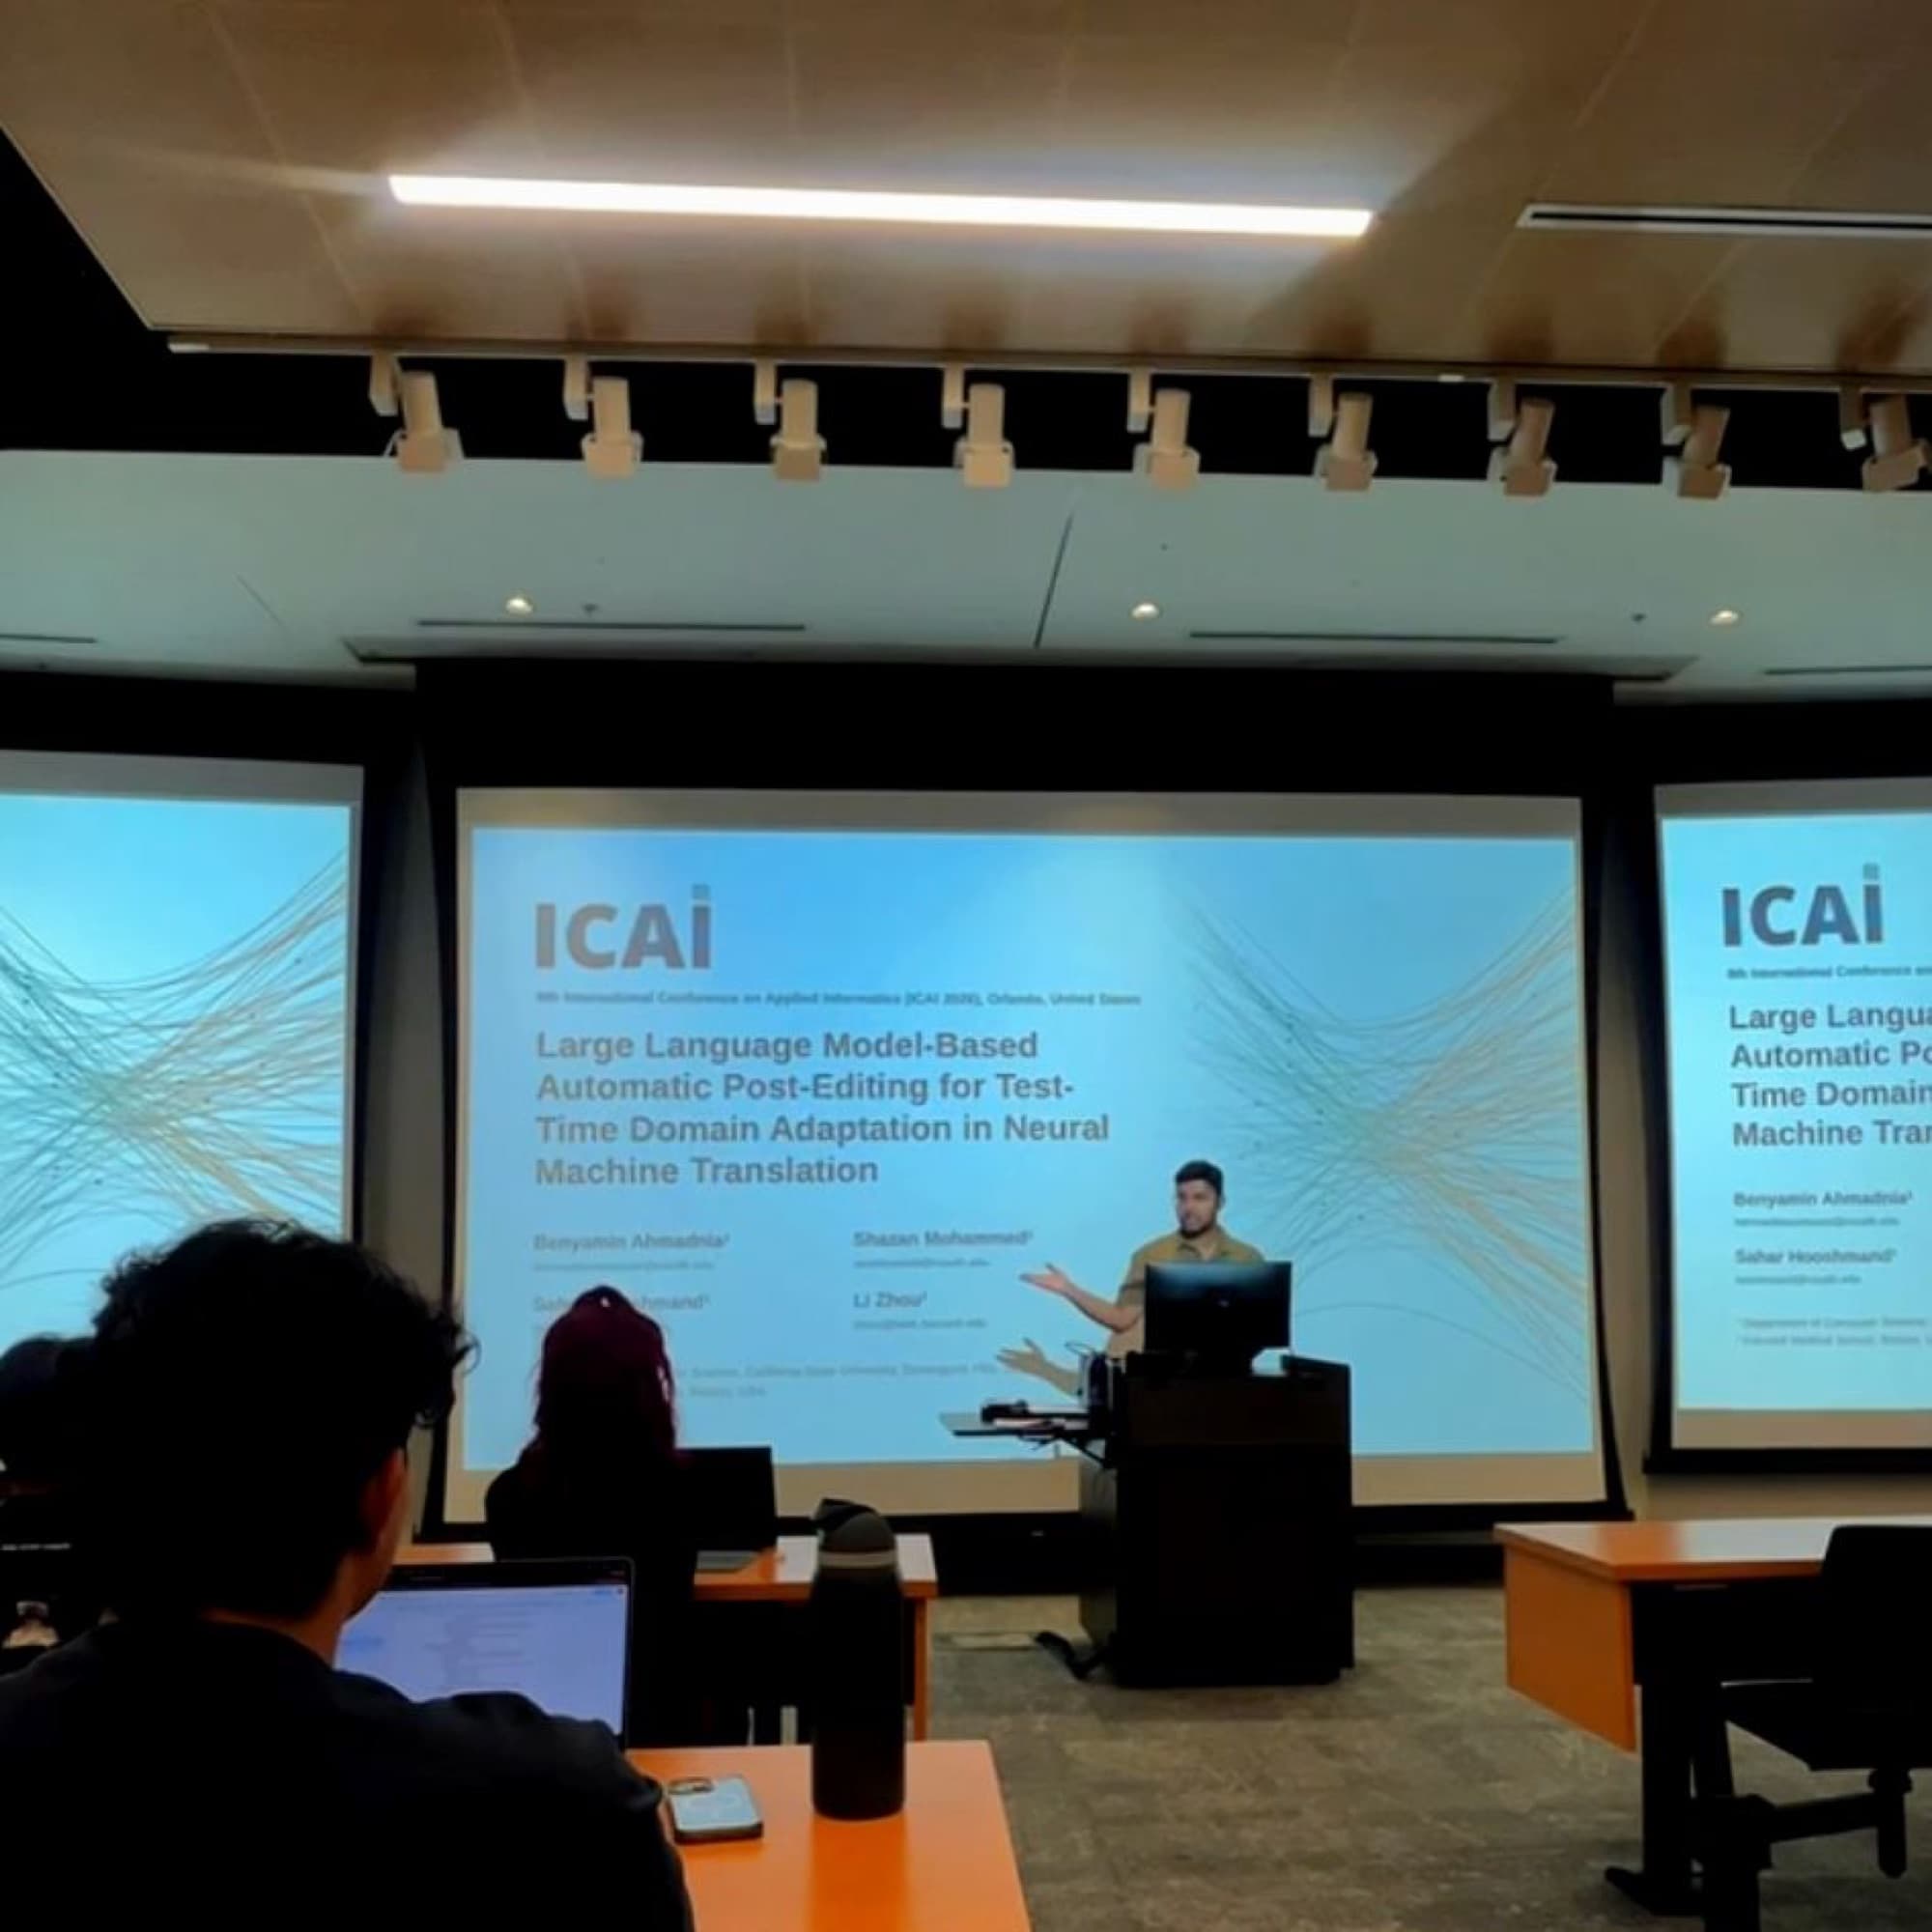
LLM post-editing · ICAI 2026
Share of the fine-tuning gain recovered, across four domains.
Pipelines
How each result was produced
Clinical textPython
English–Nepali medical domain
70k+ sentence pairsPython
Cleaned and aligned corpus
Fine-tune two modelsPyTorch · HF
mBART and NLLB-200
6 metricsMetric suite
BLEU, chrF++, METEOR, BERTScore, COMET, perplexity
Errors and ethicsHuman review
Error profiling for clinical use
70k+
sentence pairs
2
models fine-tuned
6
evaluation metrics
Outcome. NLLB-200 was more accurate and hallucinated less on clinical text.
Read the case studyProjects
A frozen translation model drafts; an LLM adapts the draft to the target domain at inference time.
87–92% of fine-tuning quality, zero retraining
Fine-tuned mBART and NLLB-200 for English–Nepali medical text, evaluated on six metrics with an ethics review.
70k+ sentence corpus · RANLP 2025
Reproduced Google Brain's pointer-network approach to the travelling salesman problem on an A100.
1.6% from optimal; critic baseline halved the gap
Live market data streamed through Kafka into a medallion lakehouse that produces positions and PnL.
Bronze → Silver → Gold, streaming to analytics
Controlled ablation of feed-forward designs in a GPT model: width, activation, and gating.
Width beat activation; SwiGLU most parameter-efficient
Grounded question-answering over business data with filtered retrieval, routing, and caching.
Grounded answers with controlled latency and cost
Research
Large language models for machine translation, evaluated with care.
ICAI 2026
Read the summary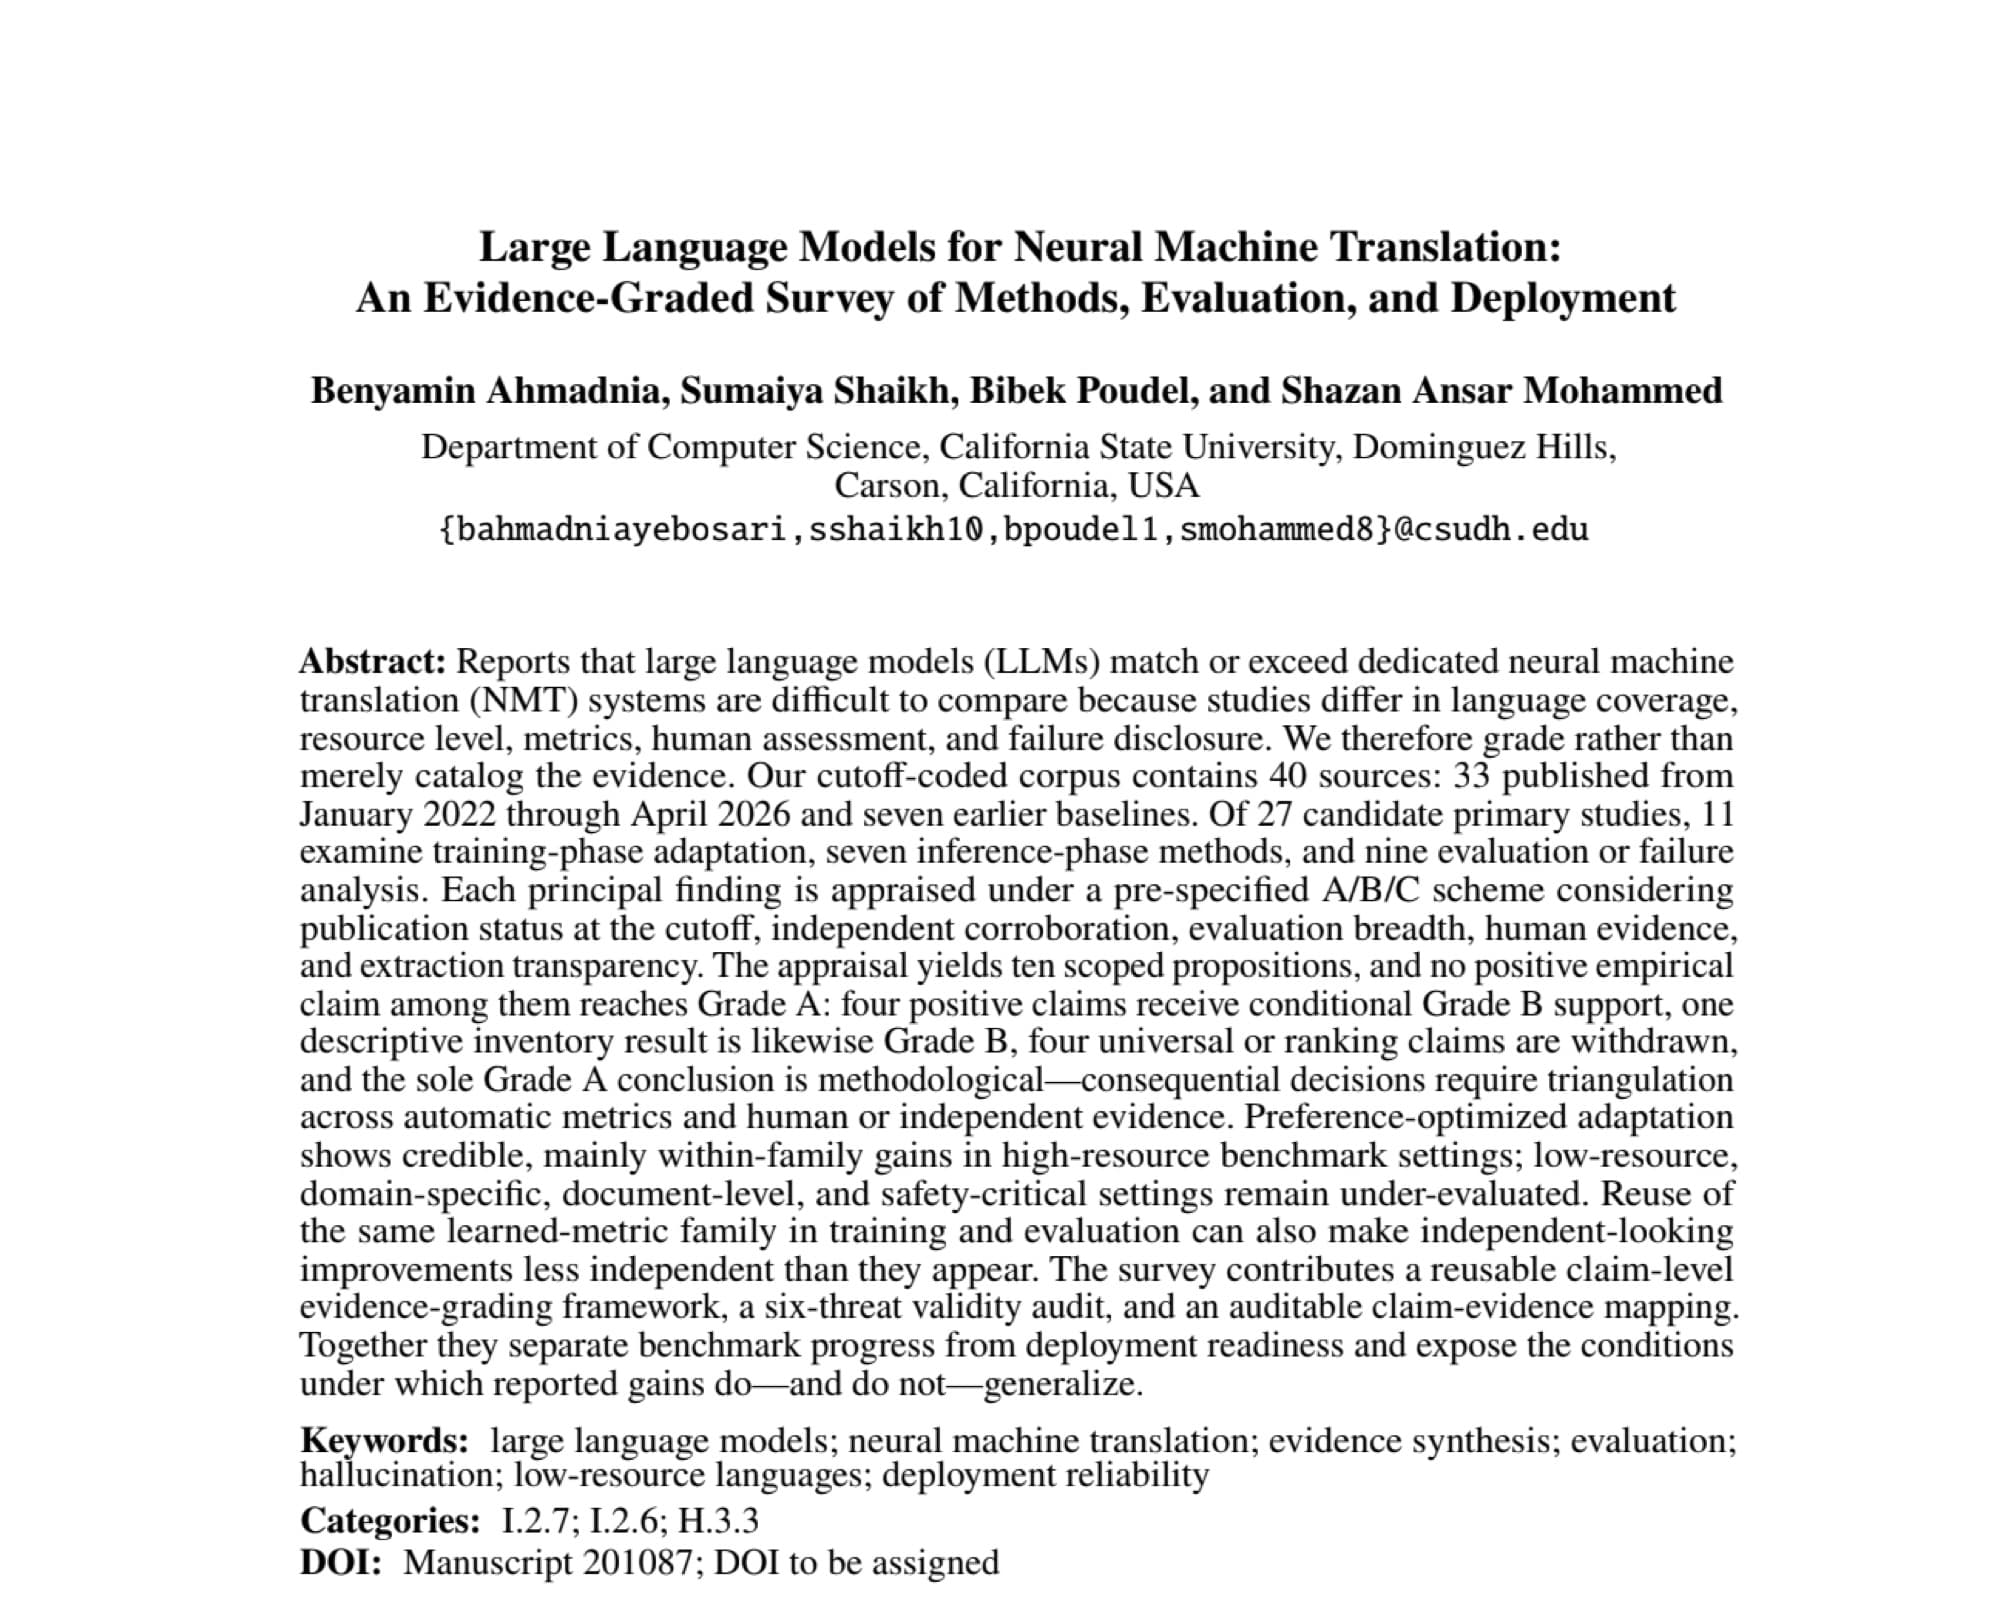
Journal of Universal Computer Science (J.UCS)
RANLP 2025
Read the summaryThesis · in progress
TRACE-MT
When does retrieval truly help LLM translation, and when is it just priming?
Grant project · in progress
LLM post-editing for Tagalog and Spanish
Norris Research Program, Fall 2026.
People
Advisors, co-authors, and the researchers I mentor.
Skills
55 skills, organized by role, from advanced to foundational.
Rigorous modeling, experimentation, and evaluation.
Advanced
Core
Foundations
Experience
California State University, Dominguez Hills
California State University, Dominguez Hills
Code for India Foundation
California State University, Dominguez Hills · GPA 4.0
 Leadership
Mahatma Gandhi Institute of Technology, Hyderabad
Life
Speaks English, Hindi, Urdu, Telugu, Arabic.
Contact
Hiring a data scientist, building a startup, or working on language AI?
